Method
Sample frames are public, machine-readable lists: the Tranco top sites list (ID 56Z8N, ranks 1 to 1,000)[1], the GSA Site Scanning inventory of live federal sites[3], the IPEDS directory of four-year institutions[4], an unofficial mirror of the Y Combinator directory used only to find B2B companies' own websites[2], and a hand-compiled list of 70 widely read English-language news sites. Government, university and SaaS slices were sampled with a seeded shuffle of 600 each; the news list is published in full.
- A named research bot fetched one page per site (two for SaaS: homepage and /pricing; help centers at help. or support. subdomains), honouring robots.txt under RFC 9309 including Crawl-delay, with a contact address in its User-Agent and no retries on refusals[5][28].
- Prose was extracted by dropping navigation, headers, footers, forms and scripts, preferring the main or article element, and keeping sentence-shaped paragraphs of at least eight words. Pages with fewer than 80 words of prose, or not in English, were excluded.
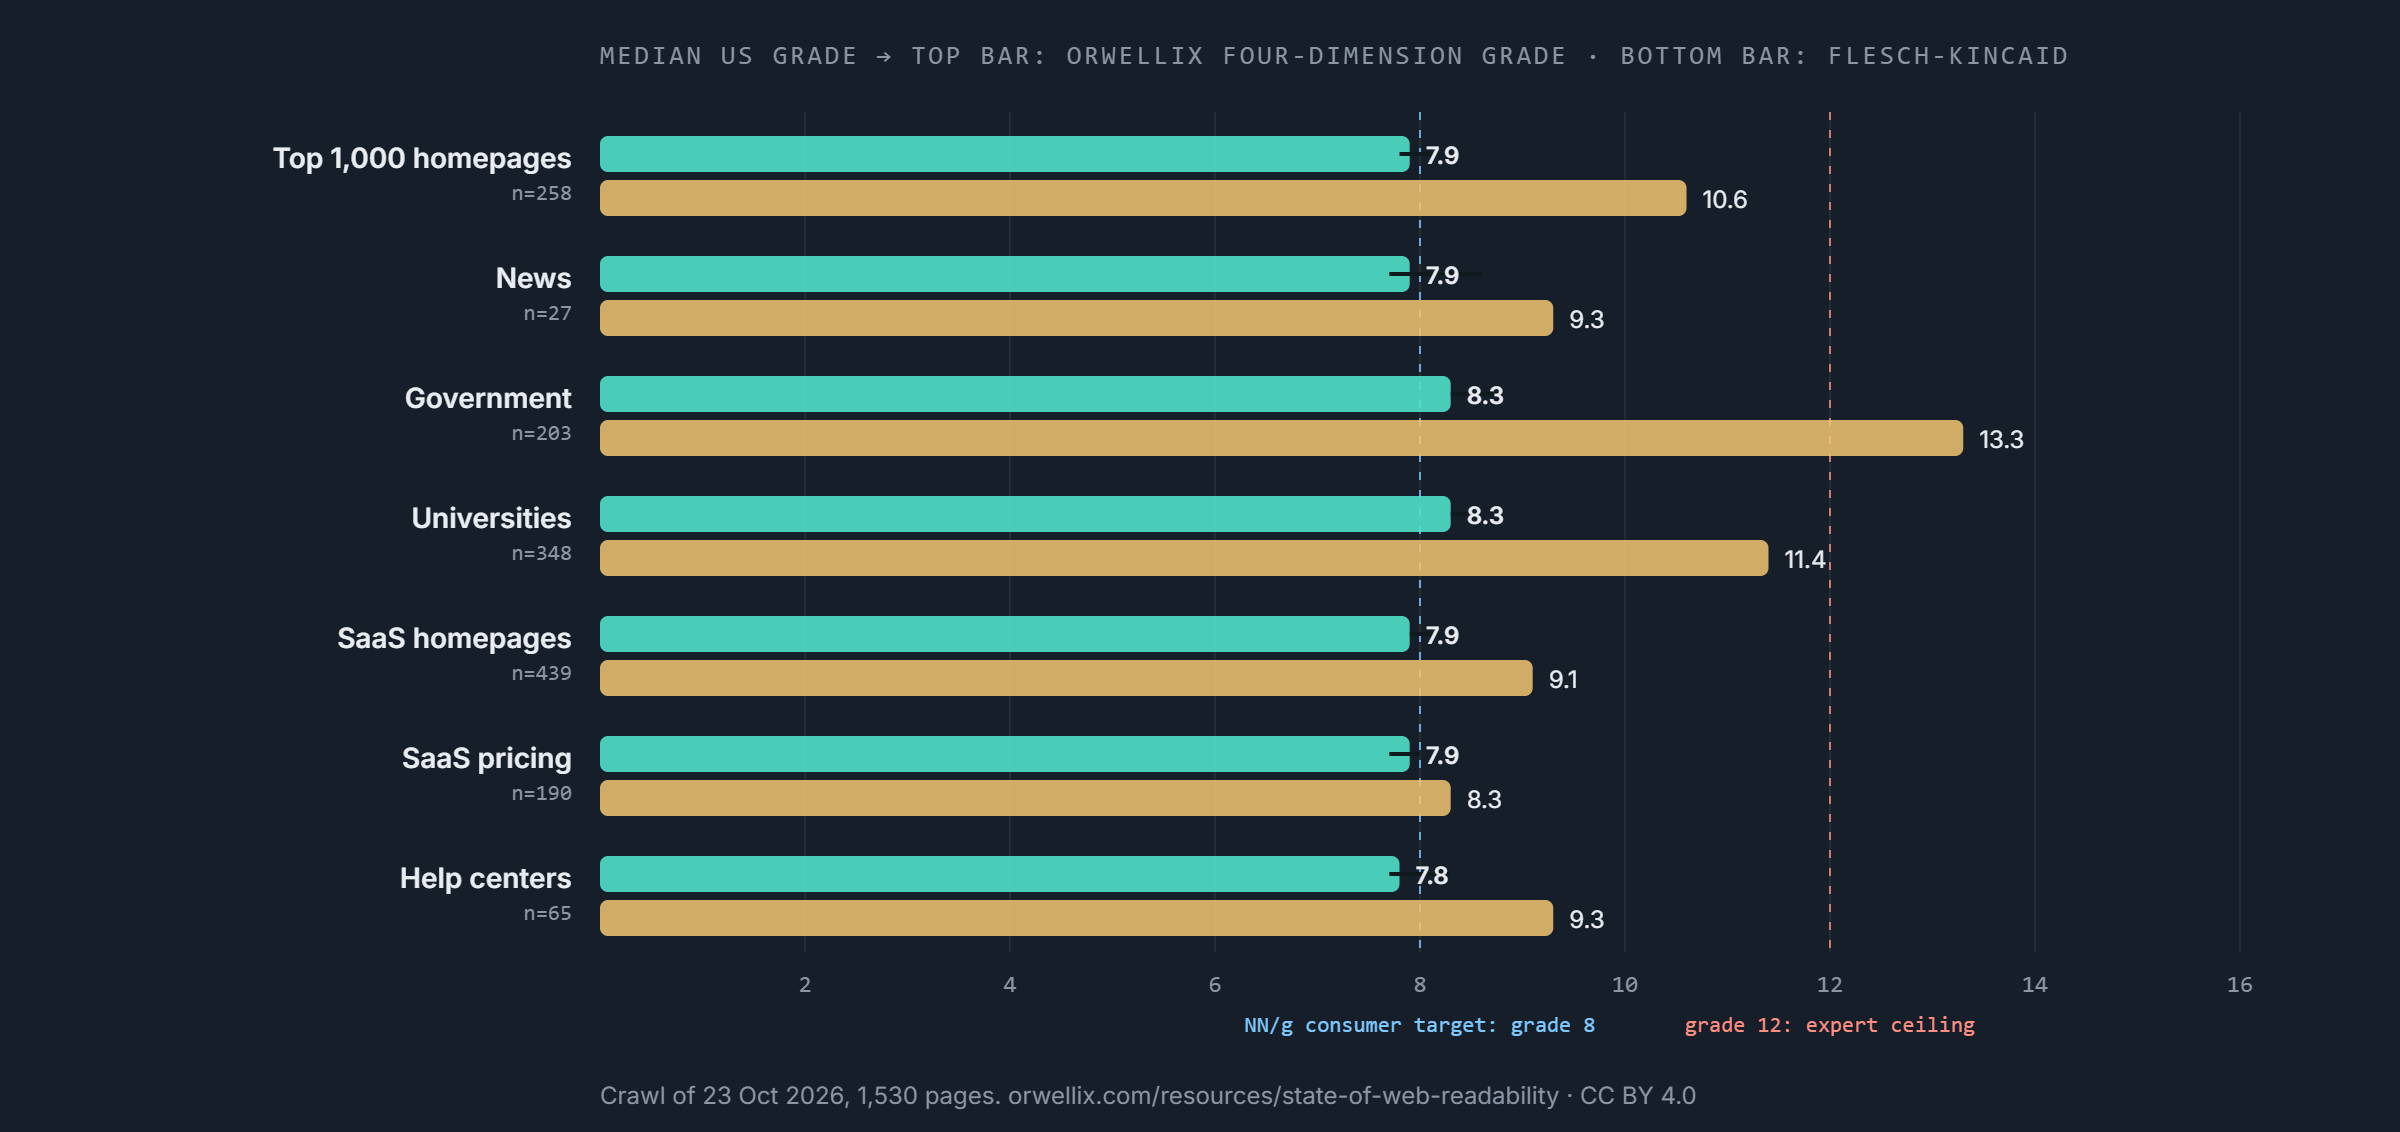
- Six formulas were computed on all extracted prose with one syllable heuristic; the passive share uses the Passive Voice Index detector; the Orwellix grade is the engine's result on the first 1,200 words.