Method
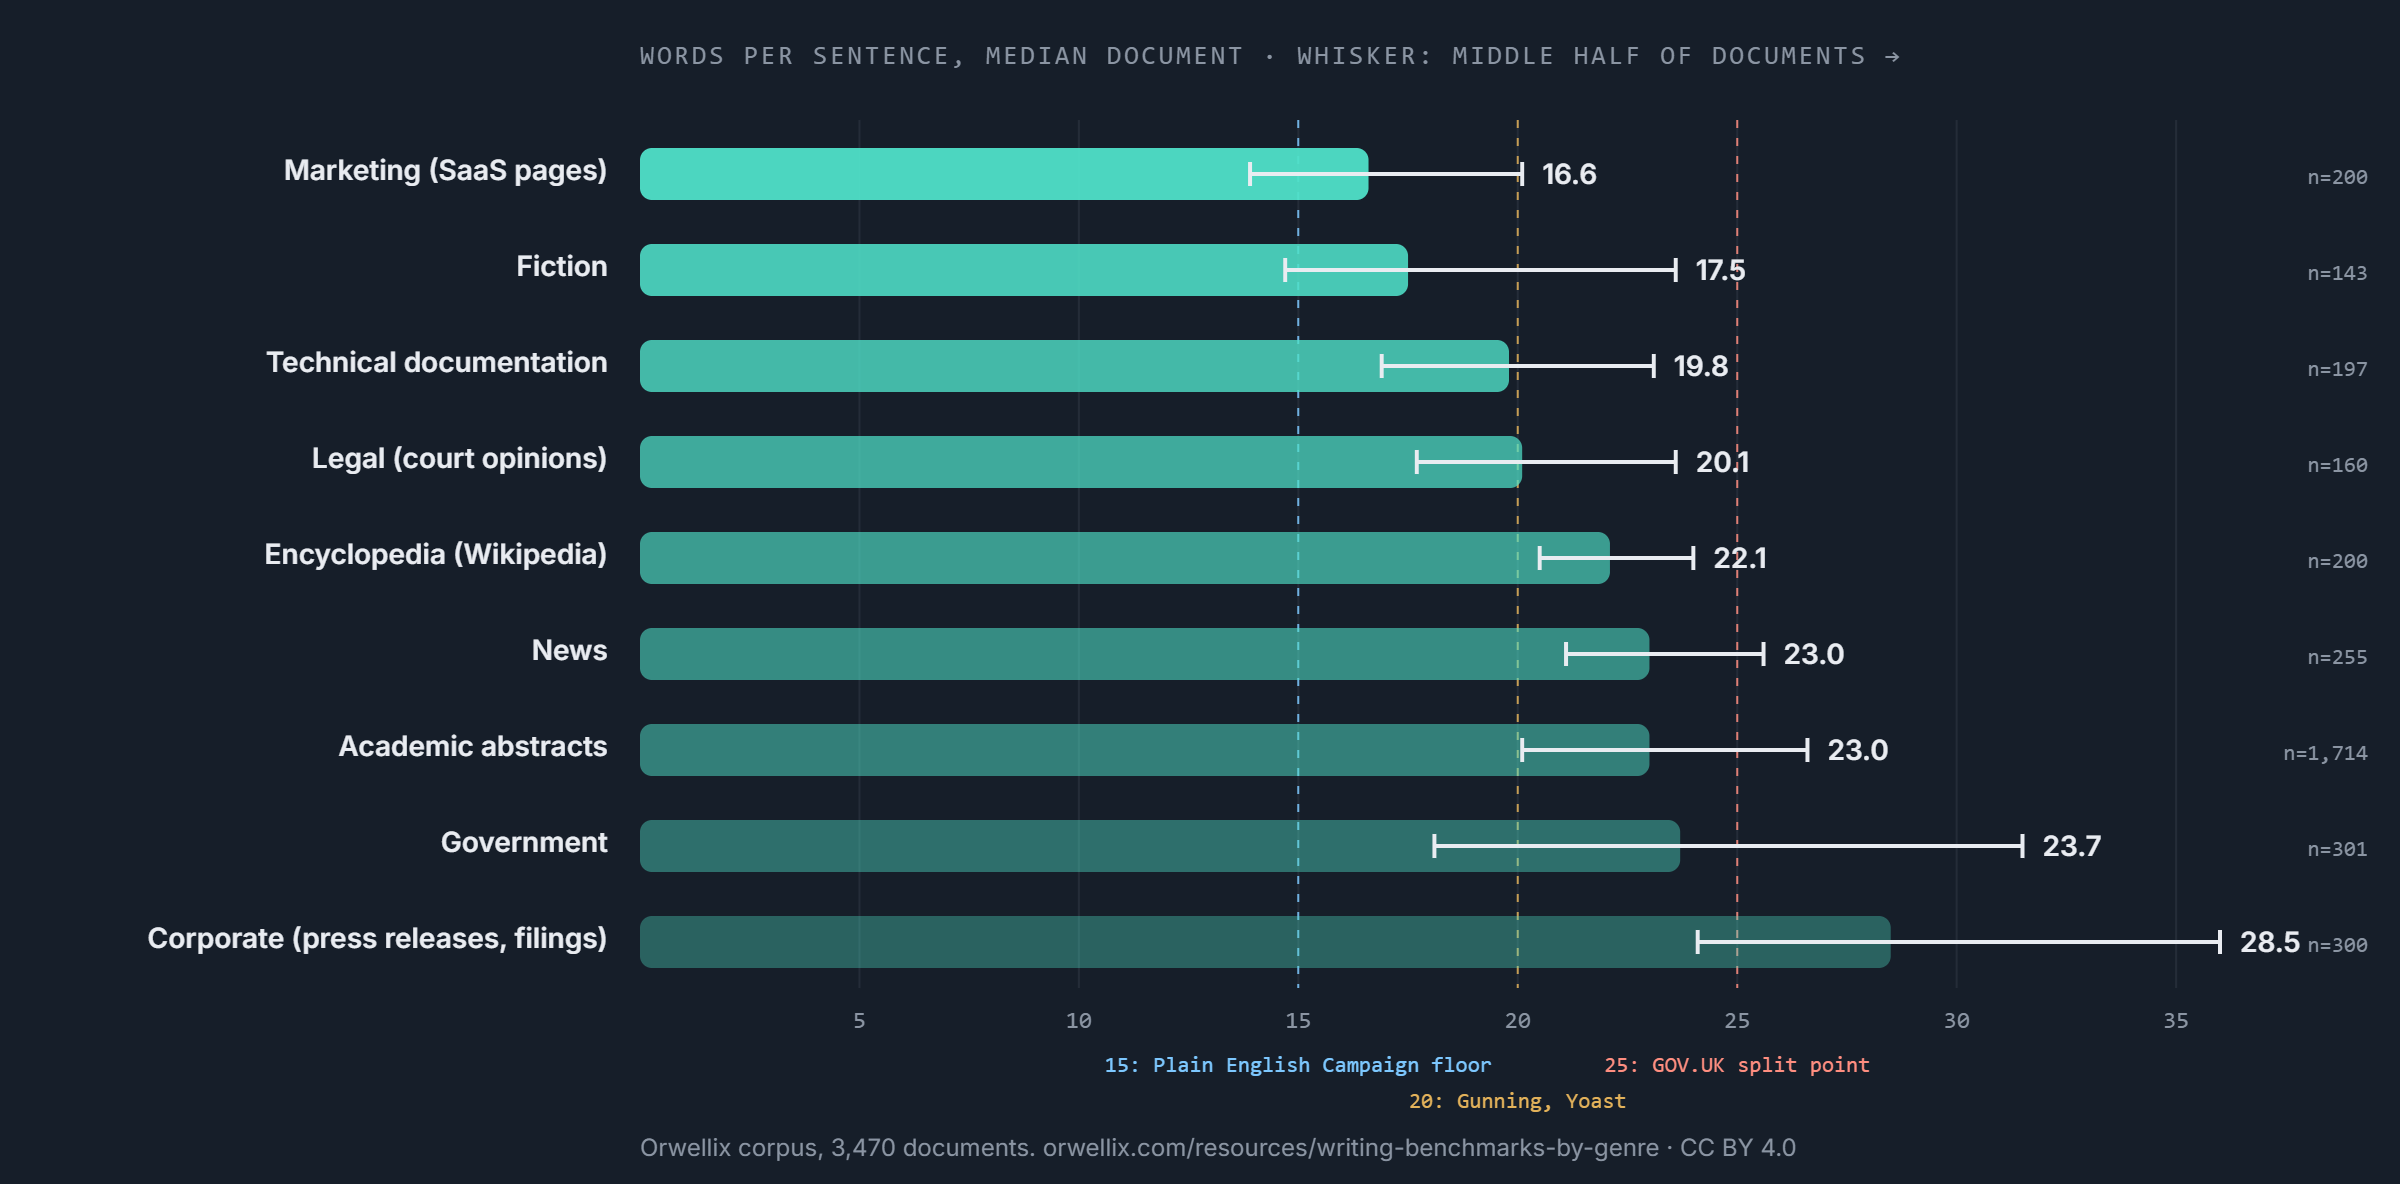
The sentence and word benchmarks use the corpus of the Passive Voice Index: 3,470 public documents in 9 genres and 27 subgenres, collected from arXiv, PubMed, OpenAlex, Project Gutenberg, Wikipedia, the Federal Register, GOV.UK, software documentation, court opinions, SEC filings, wire news and SaaS marketing pages. Every document was processed the same way.
- Sentences are split on terminal punctuation followed by a capital; headings, bullets, tables and code were removed first. Words are letter sequences; syllables use one dictionary-free heuristic for every document.
- Each measure is computed per document, then summarised as the median, quartiles and mean across documents, with a 1,000-resample bootstrap interval for sentence length, Flesch-Kincaid and passive share.
- Paragraph benchmarks come from the famous-books and web-readability corpora, where paragraph breaks survive. The Orwellix grade is measured on a seeded sample of documents per subgenre, first 1,000 words each.